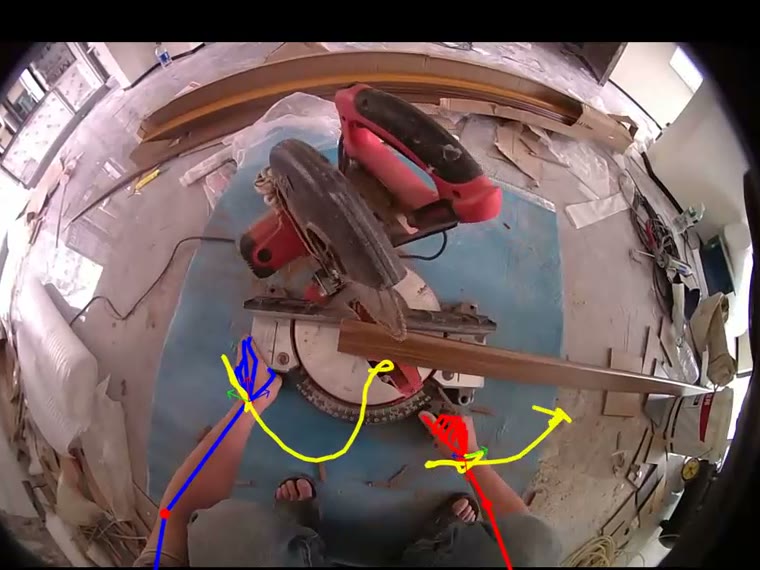
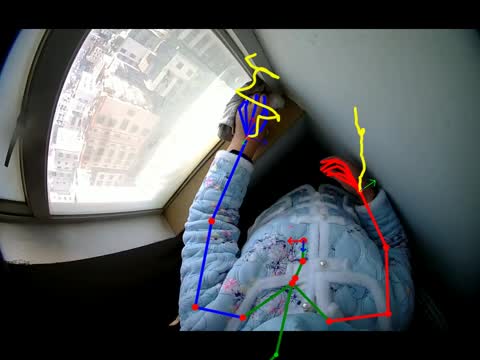
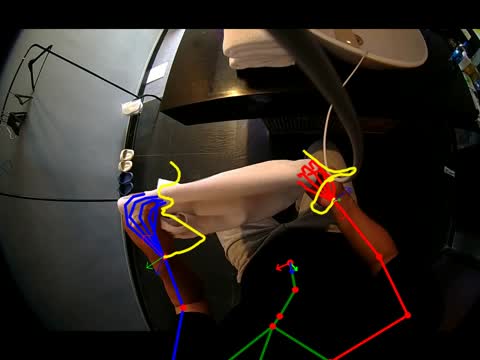
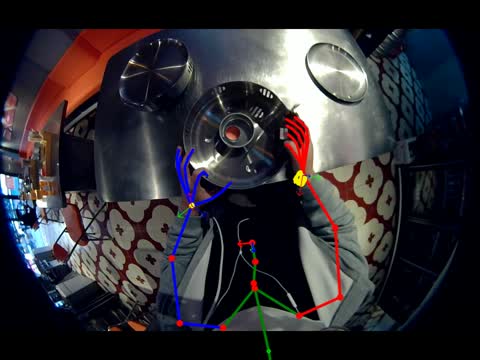
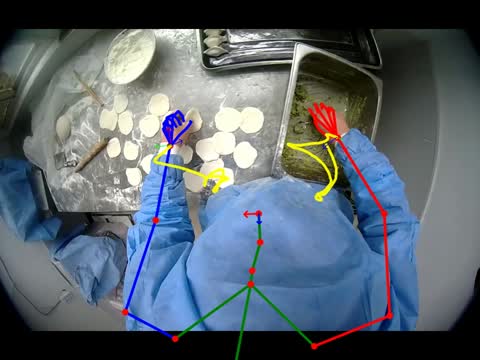
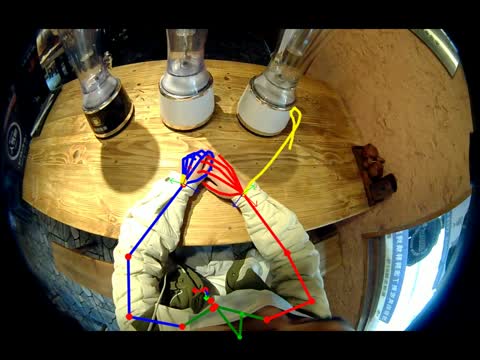
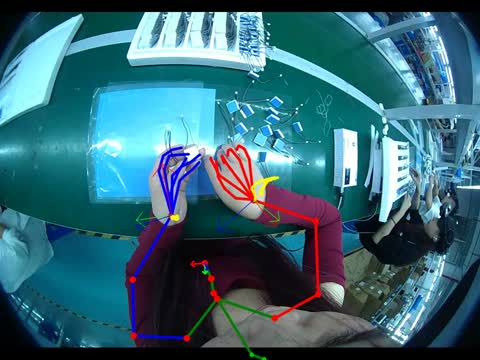
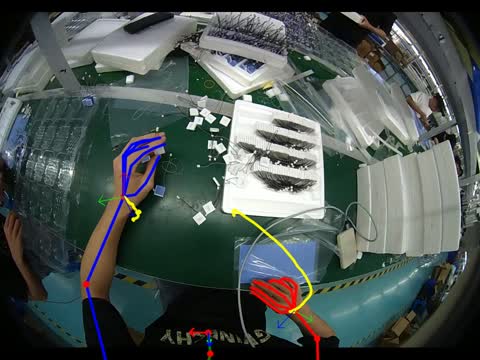
First-person capture of real human work
123,000+ verified hours
339,000+ clips · 2.42M+ annotations
aggregated & de-identified · capture-quality snapshot · 2026-06
The library
Indexed by task, not by folder.
Every clip sits in an ontology — occupation × scene × procedure. Pick an industry and pull exactly the slice you need, down to the bench it was shot at.
30s
30s
30s
30s
11s
30s
30s
30s
30s
30s
30s
30s
30s
30s
30s
30s
30s
30s
30s
30s
CNet ontology · 2,660 occupations · 299 scenes · 19,147 processes
Open the data viewer →
The annotation
One clip, taken apart.
Every object the hands touch, tracked and named. Every motion placed in 3D. Every segment written out — and the reason it followed.
objects · tracked · namedDragon fruit, foam-net bag, picking tongs — boxed per frame, not per clip.
3D pose · object topologyBody, head and hands in 3D — plus how the objects relate to each other.
action · environment · execution · inferenceFour causality layers, so a model learns why a motion followed.
plain-language segmentsWritten out on a shared timeline. Delivered LeRobot v3 / RLDS.
Capture
Hands and body, recovered in 3D.
The hand mesh placed back into a real point cloud, and full-body pose across two scenes — all recovered off ordinary first-person capture.
Research
Research and open tools.
37 ★ on GitHub
OpenCyberGlove SDK
Capture-glove SDK, open-sourced. Python API, ROS2 wrappers, Inspire-hand retargeting.
Open the repo ↗
arXiv:2609.34817 · 2026
ESTHER: Egocentric Stereo Hand Estimation and Reconstruction in the Wild
Metric 3D hand reconstruction from wearable stereo, designed for real-world egocentric capture. By Hongyu Ma, Hairong Qu, Shiqi Zhao, Yongsong Yang, and Peng Yin.
Read the paper ↗
Tell us what you're training.
What tasks, what environments, what keeps failing. We'll tell you whether we already have it.
The physical world was never written down.
We are writing it.
We're hiring
Shenzhen · Singapore · remote considered · [email protected]
Building the capture layer nobody else owns. These are open.
01Data engineeringPipeline · storage · delivery
02Capture standardsProtocol · fleet ops · field
03Quality systemsAuto QC · human review
…3D perception, and moreWrite to the address above